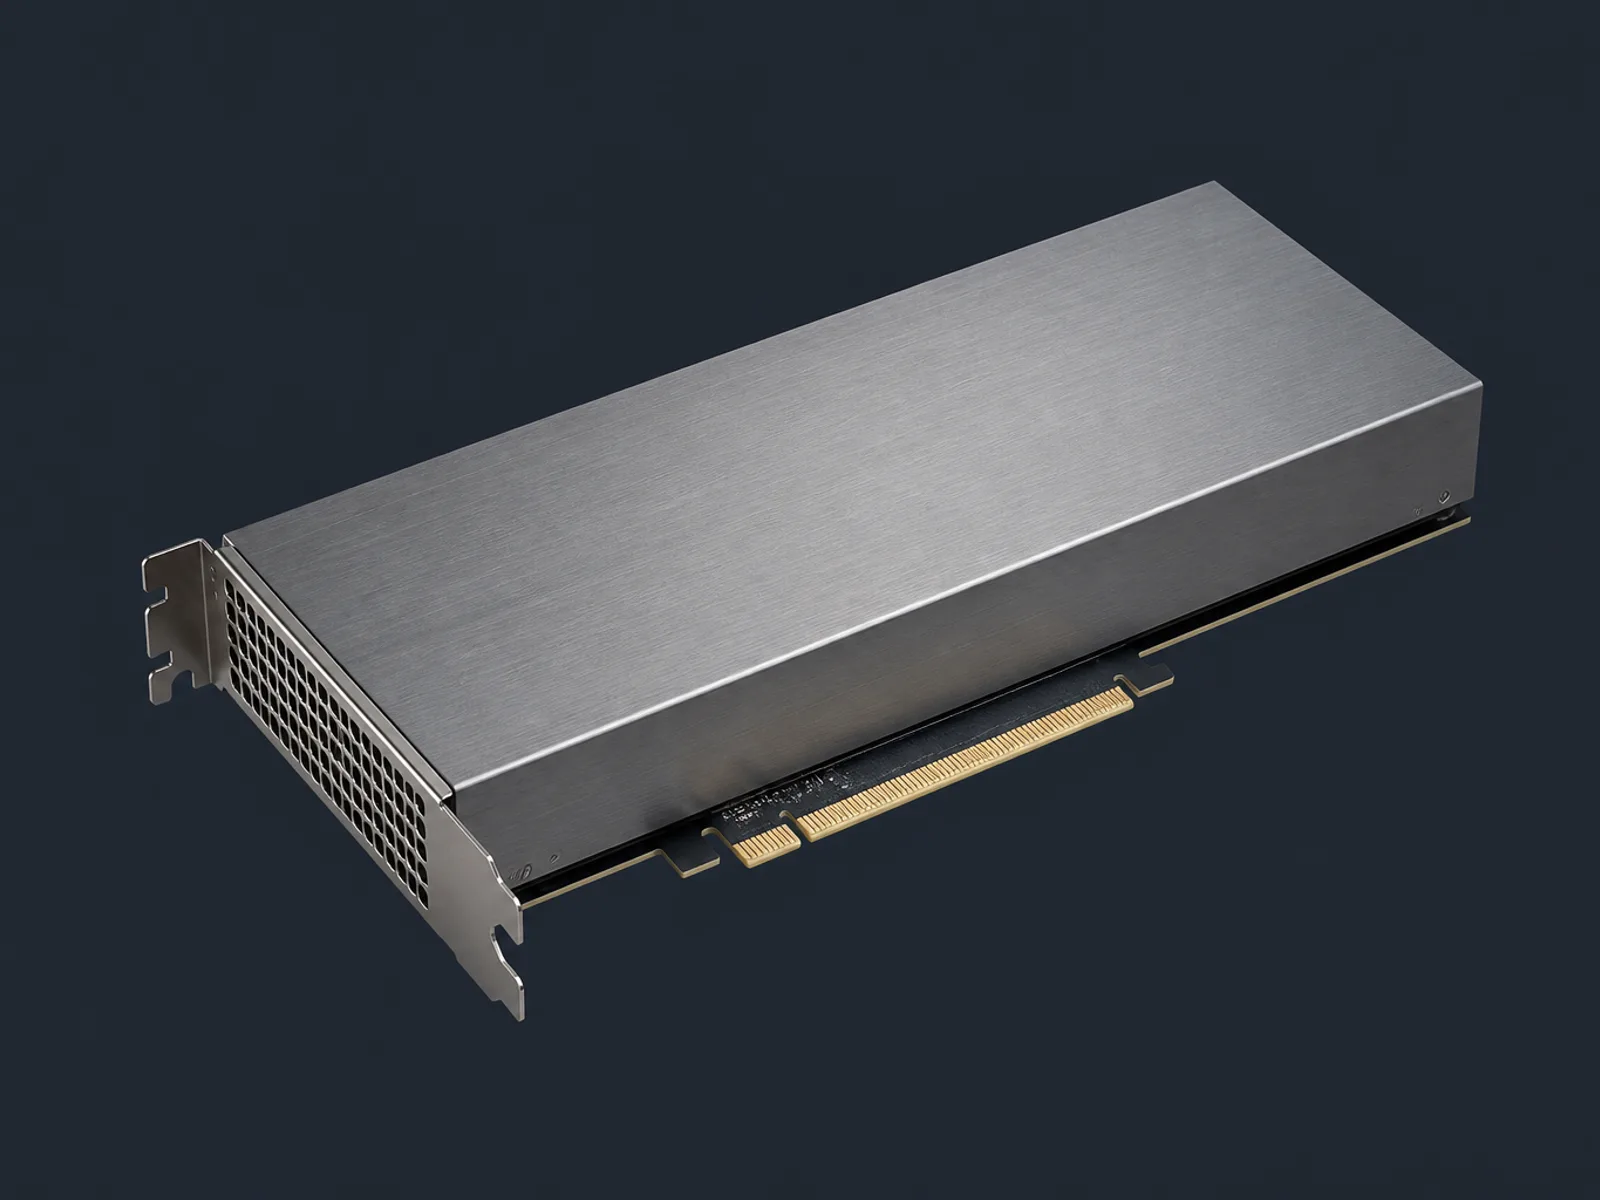
Hopper-architecture data-center GPU with 141 GB HBM3e, for large-scale training and inference.
The H200 is a Hopper-generation data-center accelerator built for large language model training and high-throughput inference. It pairs the H100's compute architecture with a substantially larger and faster HBM3e memory system, which is the limiting factor in most large-model workloads. It is supplied as an SXM5 module and is normally deployed in 8-GPU HGX baseboard configurations rather than as a standalone card.
AI trainingH200 is sourced for ai training deployments within gpus, configured to the host platform and quantity specified in your requirement.
InferenceH200 is sourced for inference deployments within gpus, configured to the host platform and quantity specified in your requirement.
HPCH200 is sourced for hpc deployments within gpus, configured to the host platform and quantity specified in your requirement.
Available as an SXM5 module or in 8-GPU HGX baseboard configurations. Quantity, cooling and host system can be specified in your requirement.
AI training · Inference · HPC
Tell us your requirement and we'll reply with sourcing options and lead time.